- What changed
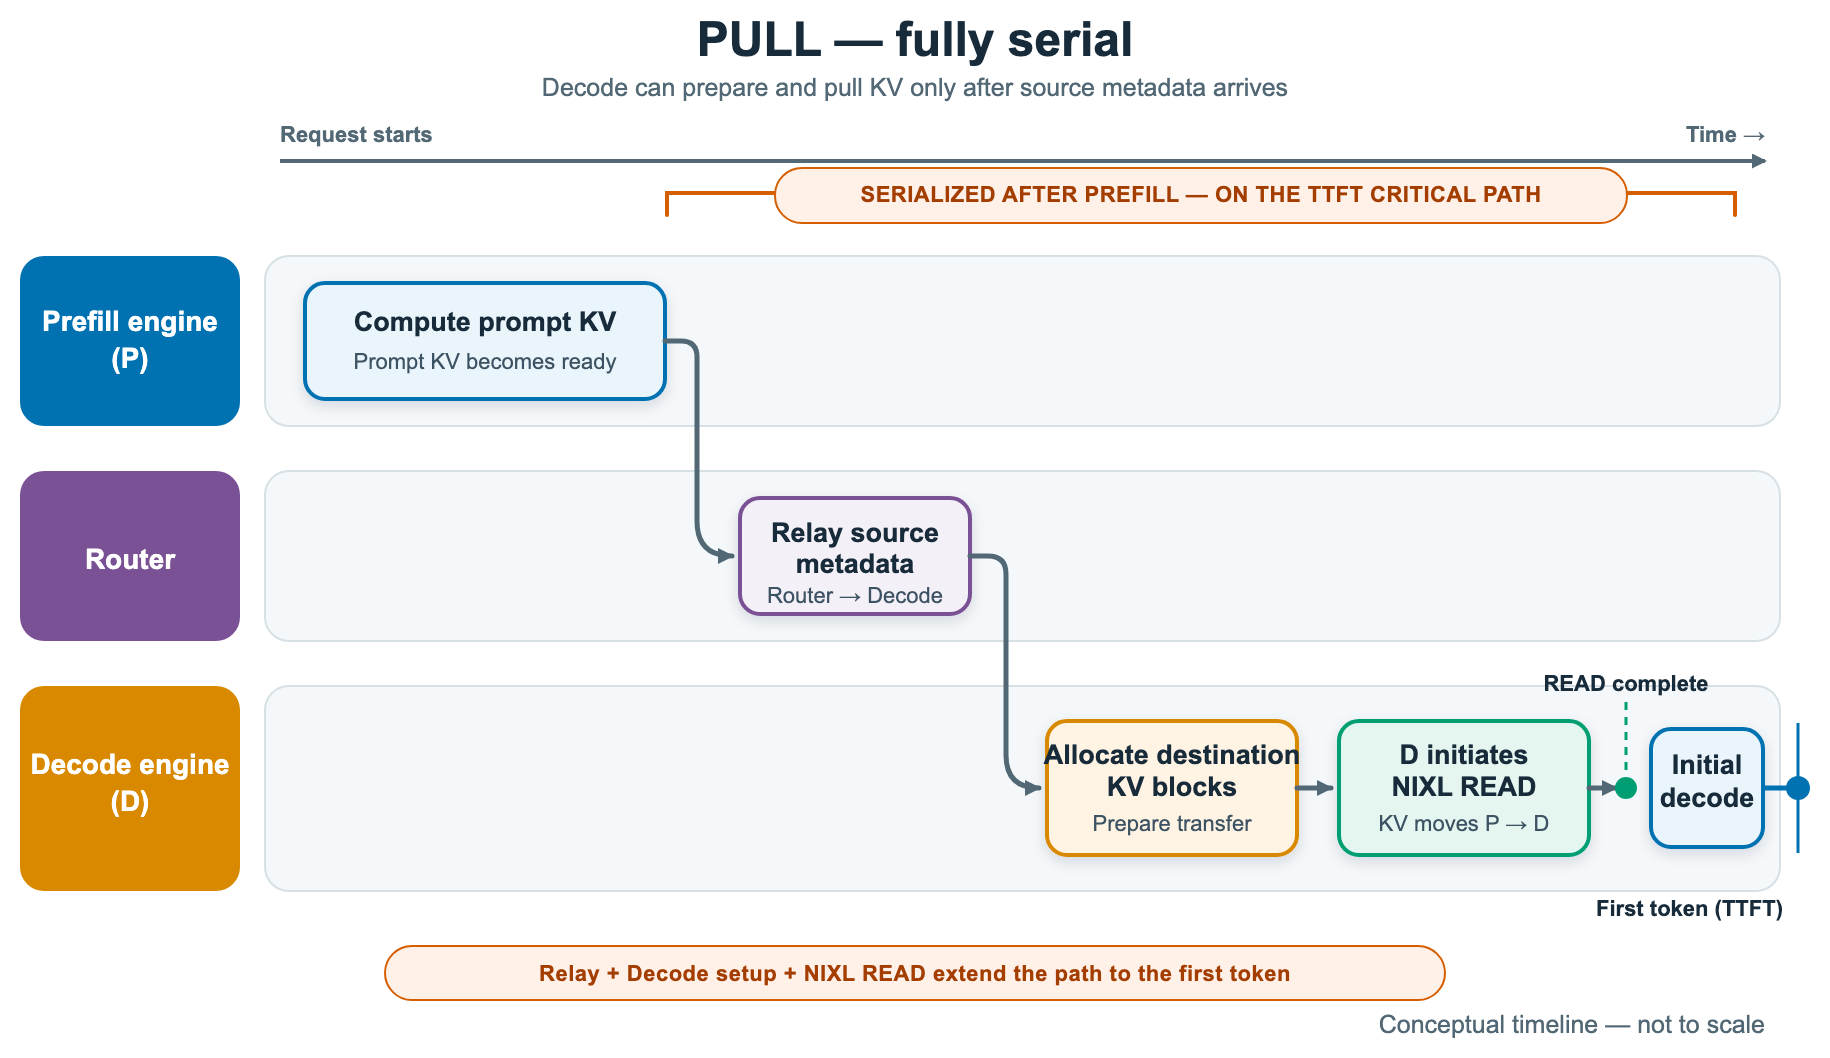
- vLLM introduces push-based KV transfer to improve time-to-first-token in disaggregated inference.
- Why you should care
- Push-based KV transfer removes sequential coordination steps from the critical path, potentially lowering TTFT.
- Your move
- Test. Evaluate if push-based transfer reduces latency in your disaggregated vLLM deployments.
- What to watch next
- Independent benchmarks comparing push-based versus pull-based KV transfer latency in production vLLM clusters.
- Event
- release
- Event date
- Oct 19, 2026
- Relevant to
- General AI readers